The problem
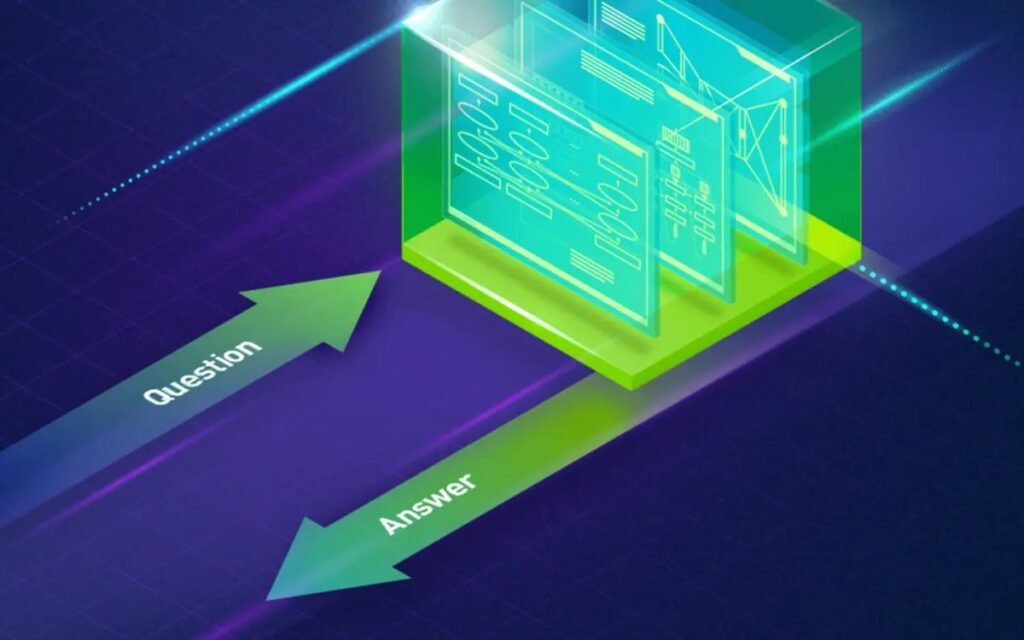
Given a question and a list of candidate sentences, decide which sentence actually answers it. This is the core of document search, support bots, and internal knowledge tools, and it is harder than keyword matching because the answer rarely repeats the words in the question.
What we built
- A labelled dataset of questions, candidate answers, and relevance labels, cleaned and tokenised for training.
- Two PyTorch models: one that attends over the document to score each candidate, and one that summarises the question before matching.
- An evaluation harness comparing the two against a baseline on held-out questions.
Why it matters
The same approach underpins the document intelligence work we do for clients: extracting the one line that matters from a contract, invoice, or report.